Why was it slow at 3am? The answer is already there.
Per-app metrics, searchable logs and the last 200 lines of a crashing app, with no stack to wire up first.
Screenshot is the real dashboard on a dev instance.
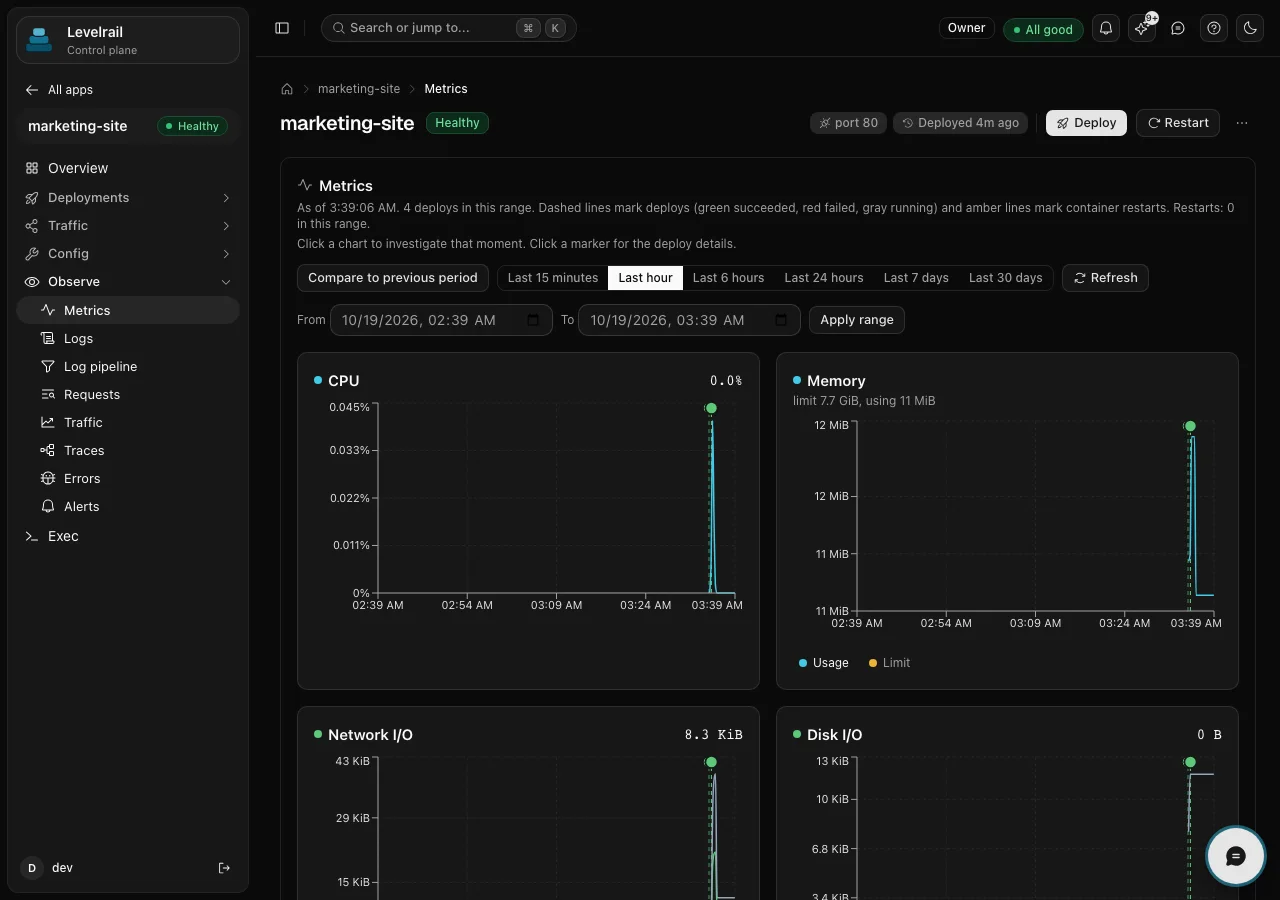
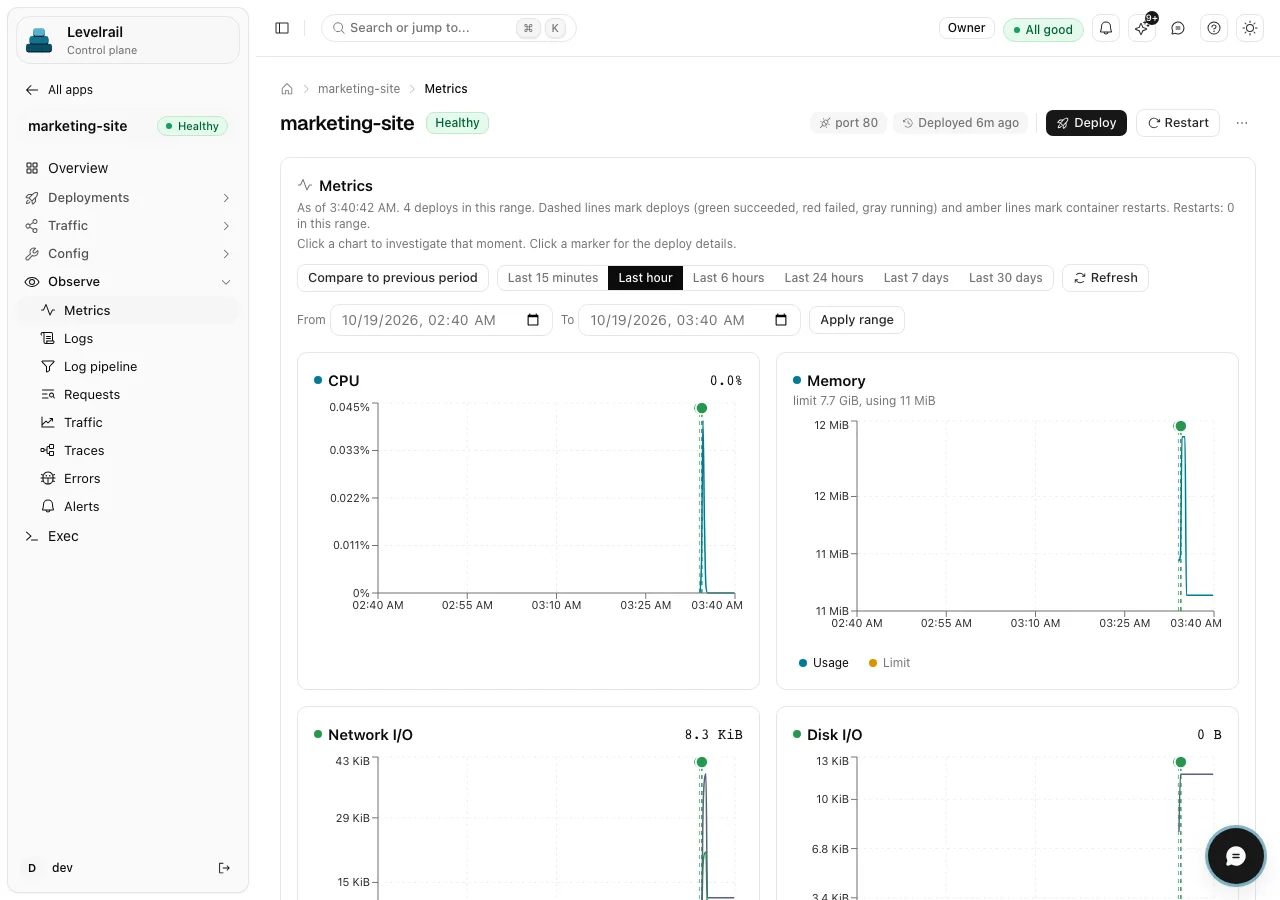
- range and compare. Last 15 minutes to 30 days, or compare with the period before.
- deploy marker. A dashed line marks each deploy, so a spike has a suspect.
- per-app charts. CPU, memory, network and disk with no setup.
Click the spike. See what changed.
Charts carry deploy markers and container restarts. Click anywhere on a chart and one panel lists what happened around that moment: deploys, config and env changes, restarts, saturation, with the likeliest cause flagged.
- 1Pick a window, or compare it with the one before. The range sits in the URL, so it is a permalink.
- 2A dashed line marks the moment a deploy landed, so a spike has an obvious suspect.
- 3CPU, memory, network and disk per app with no setup, plus request rate, errors and p50, p95, p99.
Wireframe traced from the real Metrics page.
It stays on the node.
Most platforms ship every metric and log line to one central store, and that store is what makes them heavy. Here each agent keeps its own time series and its own full-text log index. When you open a chart, the control plane asks the nodes that have the data and merges the answers.
- Pull, not push. Idle cost stays low because nothing is being shipped or centrally indexed.
- Same path on one node. The agent runs in the control plane process, so a single box and ten boxes behave alike.
- Bring your own Grafana. A Prometheus remote read endpoint is there if you want it.
- Export is opt-in. OTLP goes only to destinations you add. Design default retention is 15 days at 15 second resolution (tunable).
levelrail-cli logs failure marketing-sitestate: crashlooping, 4 restarts in the last 15mlast 200 lines of the most recently active container (tail shown)03:02:09 starting server, node v22.9.003:02:09 connecting to postgres://db.internal:5432/app03:02:10 Error: connect ECONNREFUSED 10.20.0.4:5432 at TCPConnectWrap.afterConnect (node:net:1637:16)03:02:10 fatal: database unreachable, exiting with code 1container exited (1), restartinglevelrail-cli apps alerts create marketing-site --name crashloop --kind crashloop --restart-count-threshold 3 --restart-window 10m --channel-id <id>rule created, notifies the channel with the last 200 lines attached
Example output. The app, address and times are illustrative.
When it crashloops, the log is already on screen.
Nobody should have to find the right container and race its restart timer. Levelrail tells you why an app is down without opening the log viewer.
- 3 in 15mAn app counts as crashlooping at 3 restarts in 15 minutes, both tunable.
- 200 linesThe last 200 lines of the most recently active container, with the total available.
- failed buildA failed build shows the tail of the build output instead.
- in the alertA firing crashloop alert carries the same lines. Chat channels get the last 10.
Alerts that say what changed. A status page you switch on.
Alert rules come in 14 kinds, evaluated every 30 seconds. Six of them, below.
- threshold
- One metric against a number, held for a duration you set.
- crashloop
- Container restarts inside a rolling window.
- slo_burn
- Error budget burn rate from ingress request metrics.
- cert_expiring
- Any certificate close to expiry, platform-wide or one hostname.
- backup_missing
- A database or volume backup that missed its own schedule.
- domain_health
- A domain that stopped answering.
Beta 18 notification channel kinds (email, Slack, Discord, Telegram, PagerDuty and more). Each is tested against a local fake endpoint, not yet against every real vendor.
Stable The public status page: 90 day uptime bars, incidents and maintenance, an RSS feed. It is off until you publish it and shows only the names you choose.
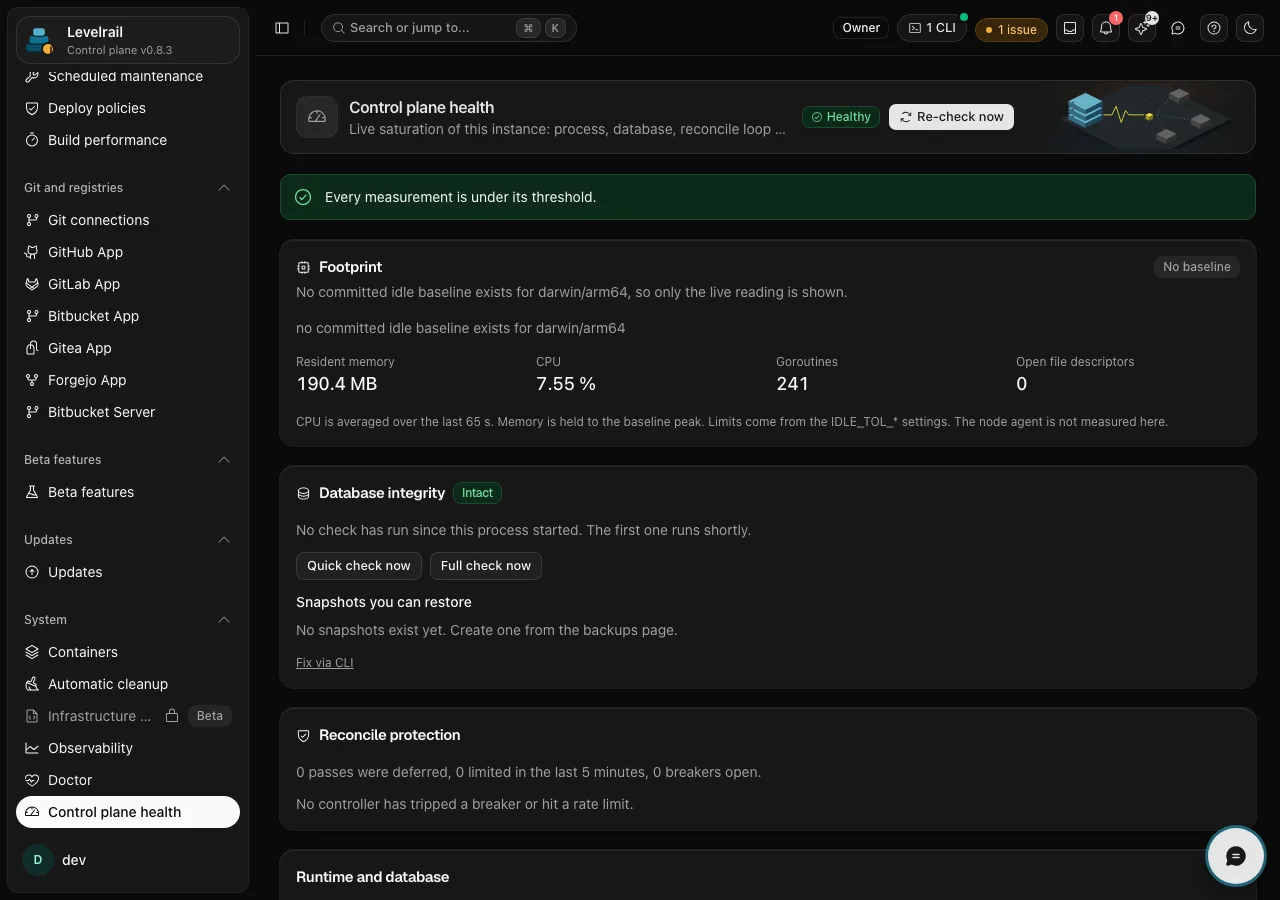
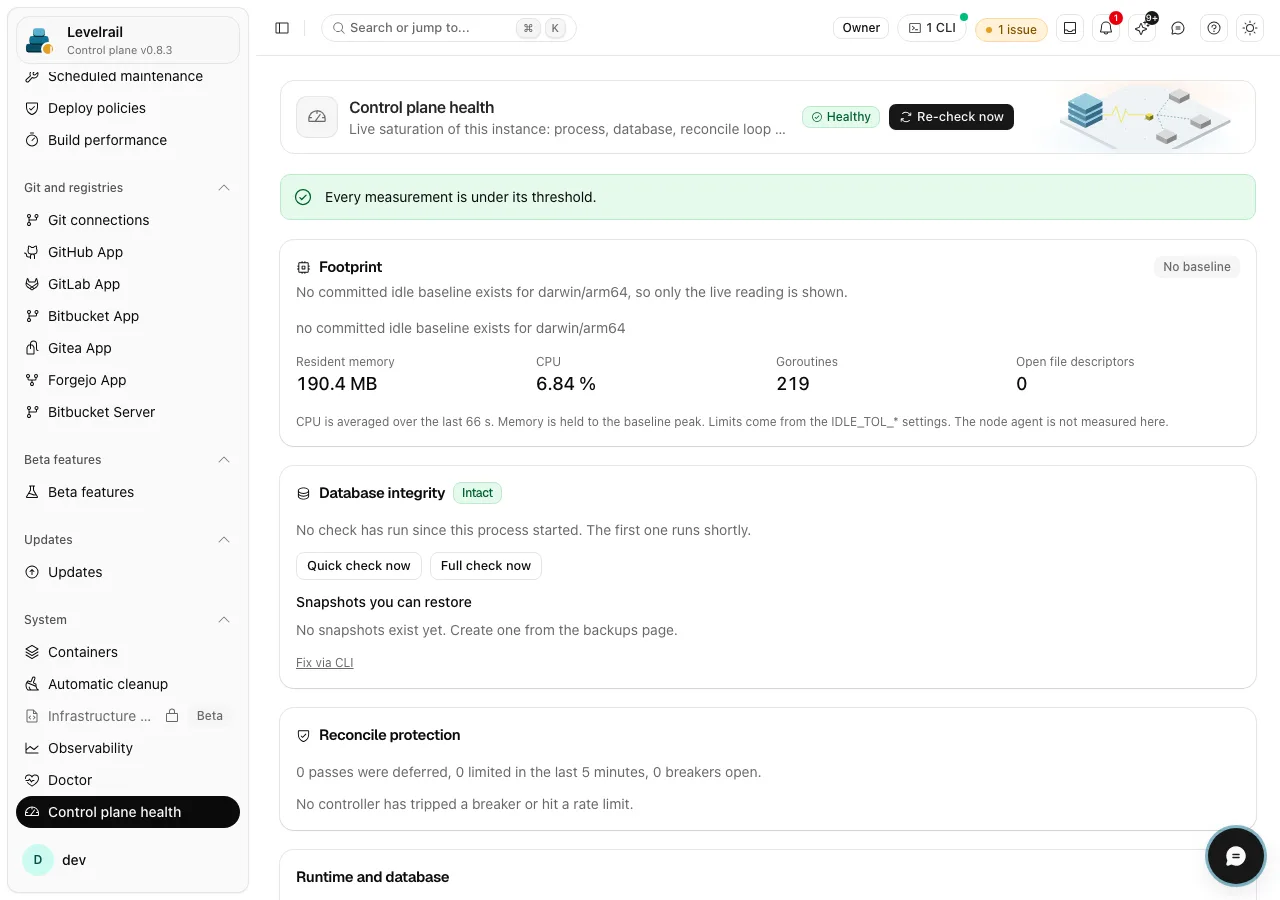
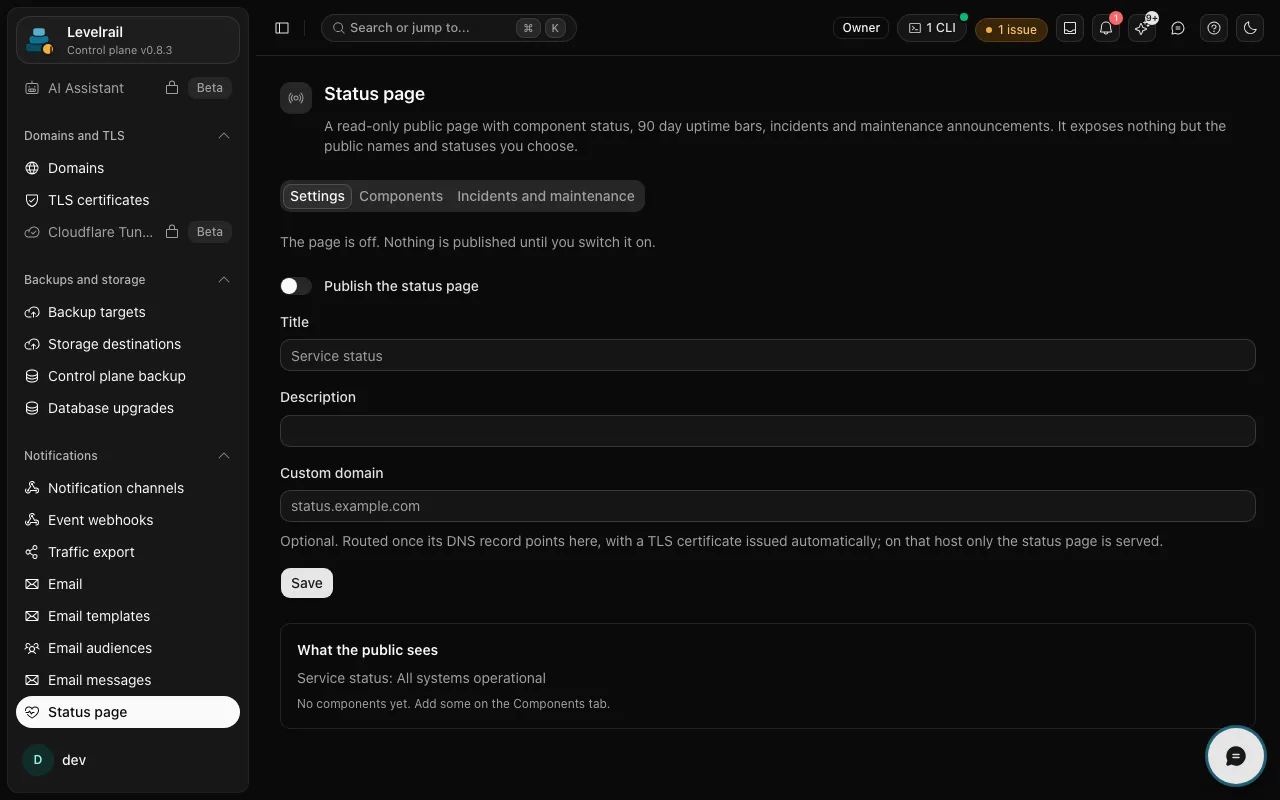
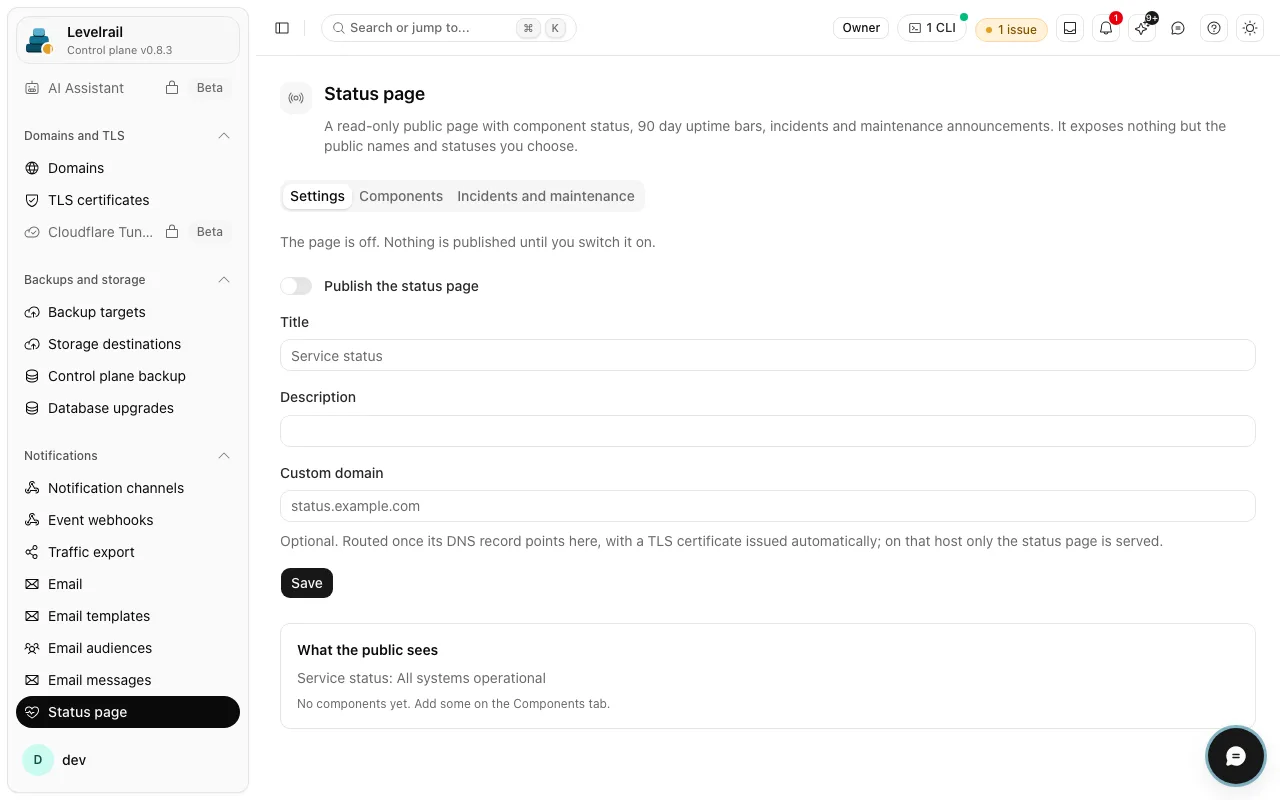
The control plane watches itself too: loops, memory and streams, each with a threshold.
See it on your own server.
One command on a Linux box, then a setup wizard. Metrics and logs start with your first app.
curl -fsSL https://levelrail.com/install.sh | sudo sh